> For the complete documentation index, see [llms.txt](https://docs.bdb.ai/data-pipeline-6/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.bdb.ai/data-pipeline-6/components/readers/gcs-reader.md).
# GCS Reader
**GCS Reader** component is typically designed to read data from Google Cloud Storage (GCS), a cloud-based object storage service provided by Google Cloud Platform. A GCS Reader can be a part of an application or system that needs to access data stored in GCS buckets. It allows you to retrieve, read, and process data from GCS, making it accessible for various use cases, such as data analysis, data processing, backups, and more.
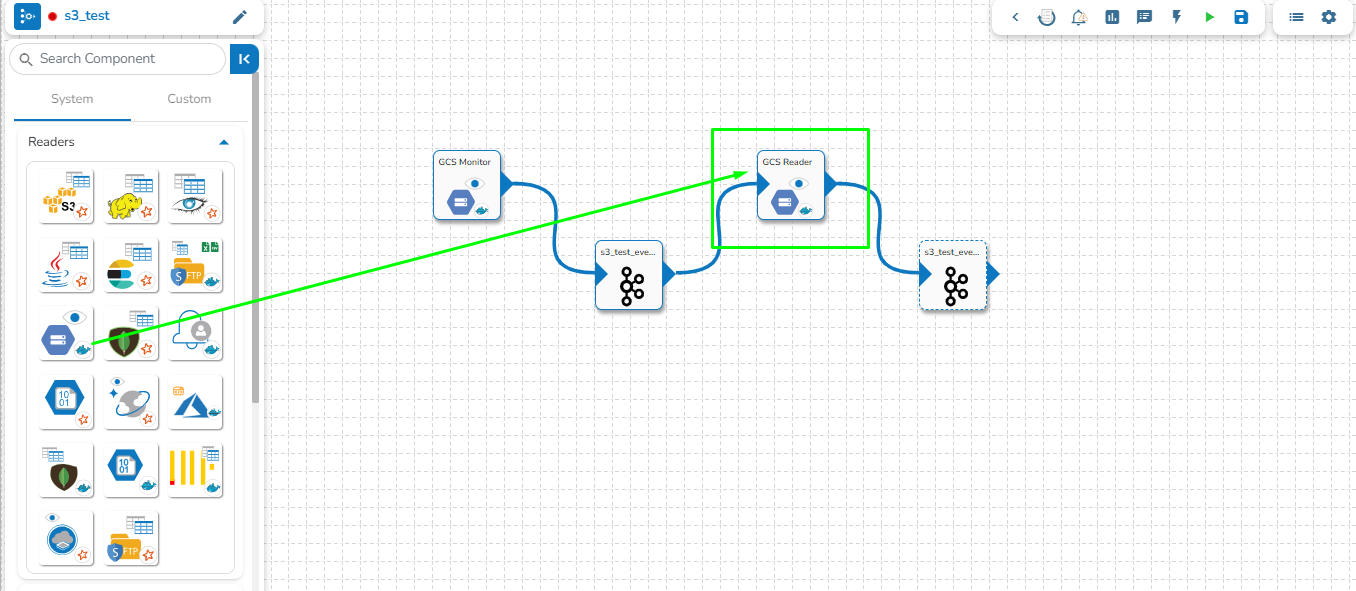
**GCS Reader** pulls data from the GCS Monitor, so the first step is to implement [GCS Monitor](https://app.gitbook.com/o/BHXEmSpD7W3xDgxnOIpk/s/c39ZvXI46qjXzpN3rYAg/~/changes/29/components/consumers/gcs-monitor).
**Note:** The users can refer to the [GCS Monitor](https://app.gitbook.com/o/BHXEmSpD7W3xDgxnOIpk/s/c39ZvXI46qjXzpN3rYAg/~/changes/29/components/consumers/gcs-monitor) section of this document for the details.
All component configurations are classified broadly into the following sections:
* [Basic Information](/data-pipeline-6/components/component-base-configuration.md)
* Meta Information
* [Resource Configuration](/data-pipeline-6/components/resource-configuration.md)
## **GCS Reader with Docker Deployment**
Configuring GCS Reader in pipeline workflow
* Navigate to the Pipeline Workflow Editor page for an existing pipeline workflow with GCS Monitor and Event component.
* Open the Reader section of the Component Pallet.
* Drag the GCS Reader to the Workflow Editor.
* Click on the dragged ***GCS Reader*** component to get the component properties tabs below.
### **Basic Information**
It is the default tab to open for the component while configuring it.
* **Invocation Type:** Select an invocation mode from the ‘Real-Time’ or ‘Batch’ using the drop-down menu.
* **Deployment Type:** It displays the deployment type for the reader component. This field comes pre-selected.
* **Container Image Version:** It displays the image version for the docker container. This field comes pre-selected.
* **Failover Event:** Select a failover Event from the drop-down menu.
* **Batch Size (min 10):** Provide the maximum number of records to be processed in one execution cycle (the minimum limit for this field is 10).
Basic Infomration tab with Docker Deployment Type
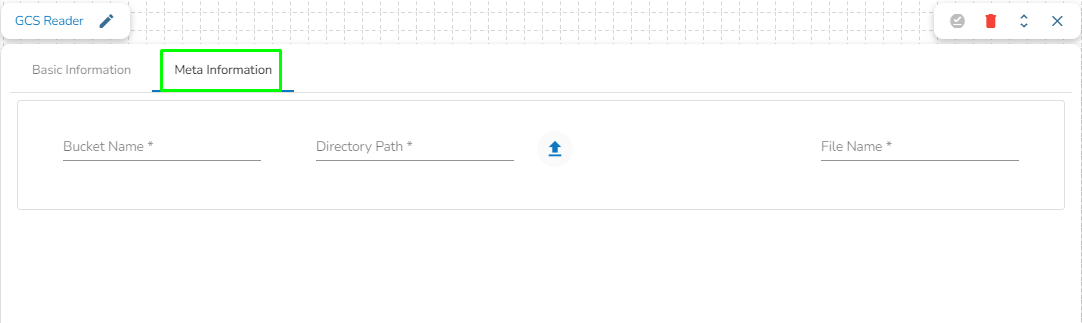
### **Steps to Configure the Meta Information of GCS Reader (with Docker Deployment Type)**
* **Bucket Name:** Enter the Bucket name for GCS Reader. A bucket is a top-level container for storing objects in GCS.
* **Directory Path:** Enter the path where the file is located, which needs to be read.
* **File Name:** Enter the file name.
Meta information tab of GCS Reader (with Docker Type)
## PySpark GCS Reader
* Navigate to the Pipeline Workflow Editor page for an existing pipeline workflow with the PySpark GCS Reader and Event component.
OR
* You may create a new pipeline with the mentioned components.
* Open the Reader section of the Component Pallet.
* Drag the PySpark GCS Reader to the Workflow Editor.
* Click the dragged ***GCS Reader*** component to get the component properties tabs below.
### Basic Information
* **Invocation Type:** Select an invocation mode from the ‘Real-Time’ or ‘Batch’ using the drop-down menu.
* **Deployment Type:** It displays the deployment type for the reader component. This field comes pre-selected.
* **Container Image Version:** It displays the image version for the docker container. This field comes pre-selected.
* **Failover Event:** Select a failover Event from the drop-down menu.
* **Batch Size (min 10):** Provide the maximum number of records to be processed in one execution cycle (the minimum limit for this field is 10).
Basic Infomration tab with Spark Deployment Type
### **Steps to configure the Meta Information of GCS Reader (with Spark Deployment Type)**
* **Secret File** (\*): Upload the JSON from the Google Cloud Storage.
* **Bucket Name** (\*): Enter the Bucket name for GCS Reader. A bucket is a top-level container for storing objects in GCS.
* **Path**: Enter the path where the file is located, which needs to be read.
* ***Read Directory***: Disable reading single files from the directory.
* ***Limit***: Set a limit for the number of records to be read.
* ***File-Type***: Select the File-Type from the drop-down.
* **File Type** (\*): Supported file formats are:
* **CSV**: The Header, Multilibe, and Infer Schema fields will be displayed with CSV as the selected File Type. Enable the Header option to get the Header of the reading file and enable the Infer Schema option to get the true schema of the column in the CSV file. Check the Multiline option if there is any Multiline string in the file.
* **JSON**: The Multiline and Charset fields are displayed with JSON as the selected File Type. Check in the Multiline option if there is any Multiline string in the file.
* **PARQUET**: No extra field gets displayed with PARQUET as the selected File Type.
* **AVRO**: This File Type provides two drop-down menus.
* **Compression**: Select an option out of the Deflate and Snappy options.
* **Compression Level**: This field appears for the Deflate compression option. It provides 0 to 9 levels via a drop-down menu.
* **XML**: Select this option to read the XML file. If this option is selected, the following fields will be displayed:
* Infer schema: Enable this option to get the true schema of the column.
* Path: Provide the path of the file.
* Root Tag: Provide the root tag from the XML files.
* Row Tags: Provide the row tags from the XML files.
* Join Row Tags: Enable this option to join multiple row tags.
* ***Query***: Enter the Spark SQL query.
Select the desired columns using the ***Download Data*** and ***Upload File*** options.
* [x] **Upload File**: The user can upload the existing system files (CSV, JSON) using the ‘**Upload File**’ icon (file size must be less than 2 MB).
* [x] **Download Data (Schema)**: Users can download the schema structure in JSON format using the ‘**Download Data**’ icon.
**Or**
The user can also use the ***Column Filter*** section to select columns.
## Saving the Component Configuration
* Click the ***Save Component in Storage*** icon after doing all the configurations to save the reader component.

* A notification message appears to inform about the component configuration success.